GPU Gateway
Shared GPU inference with budgets and fallbacks
One gateway in front of every GPU workload. Applications call it instead of a GPU provider; it handles access, quotas, caching, queuing and cost, and sends the work to rented serverless GPUs or to hardware we own.
What It Is
GPU Gateway sits between the applications that need GPU work done (the callers) and the places that do it. Each caller has its own token, priority, rate limit and daily budget. Each service, starting with indexing text for AI search, has an ordered list of providers, from rented serverless GPUs to agents on machines we own, and the gateway sends each job to the first one that is healthy and has room.
Jobs can be answered straight away or queued, and failed jobs are retried and kept for inspection. Capacity is capped per provider, so a borrowed workstation and a rented GPU pool are capped independently, and an agent stops offering capacity while its owner needs the GPU. Warm capacity on metered providers is shown as billed, and can be released from the admin console.
Inside GPU Gateway
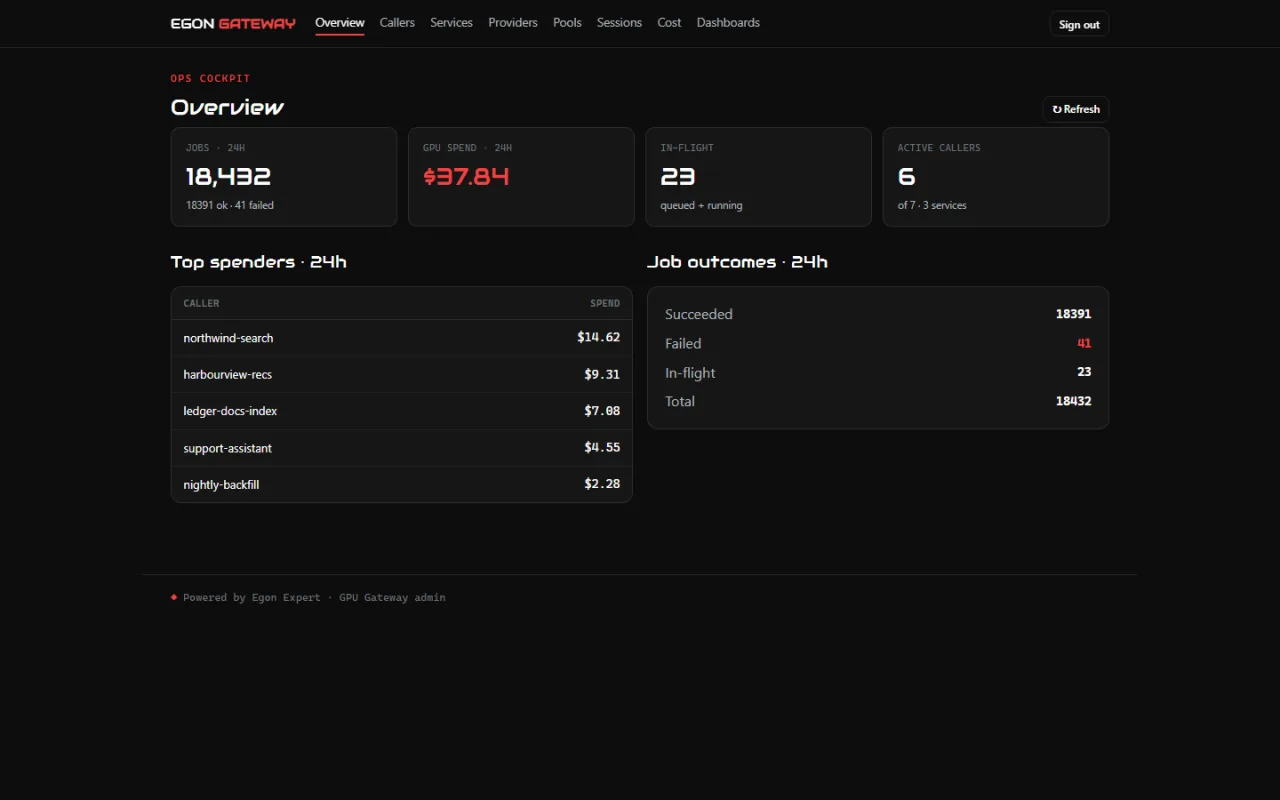
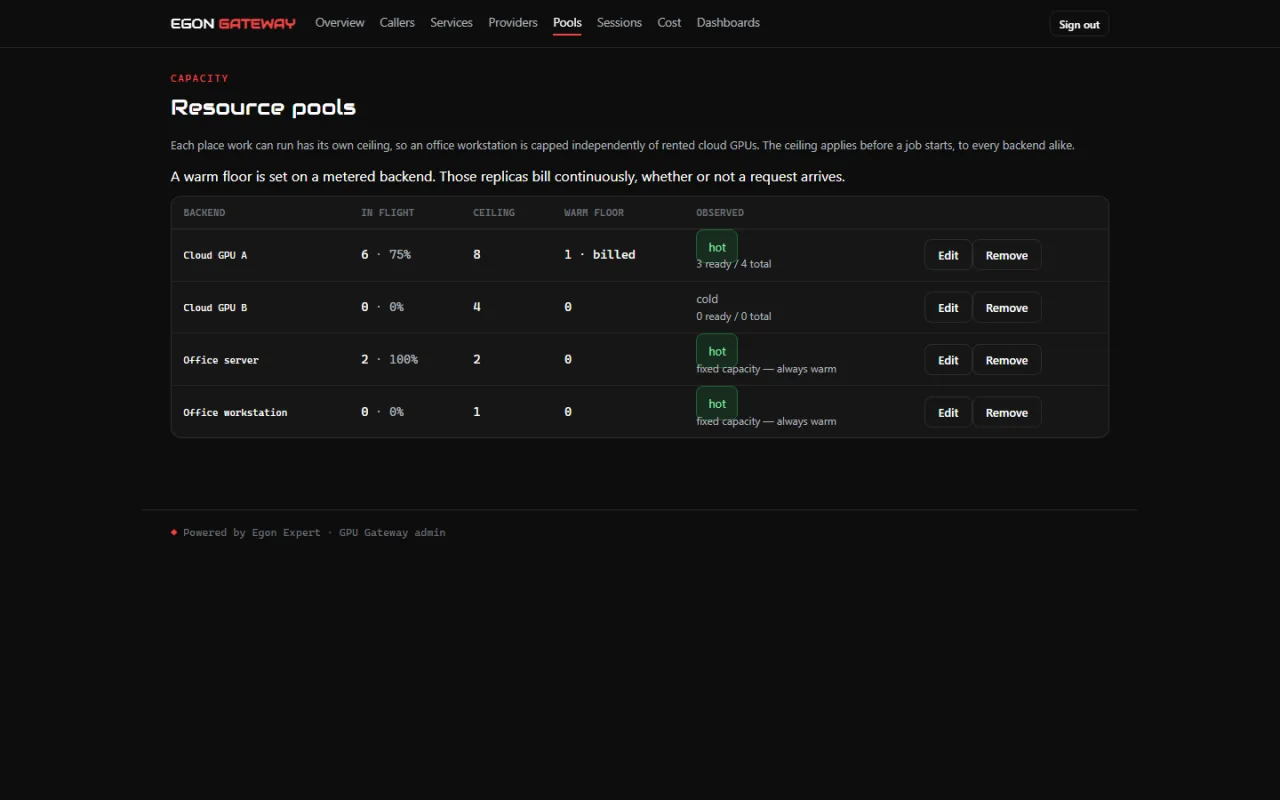
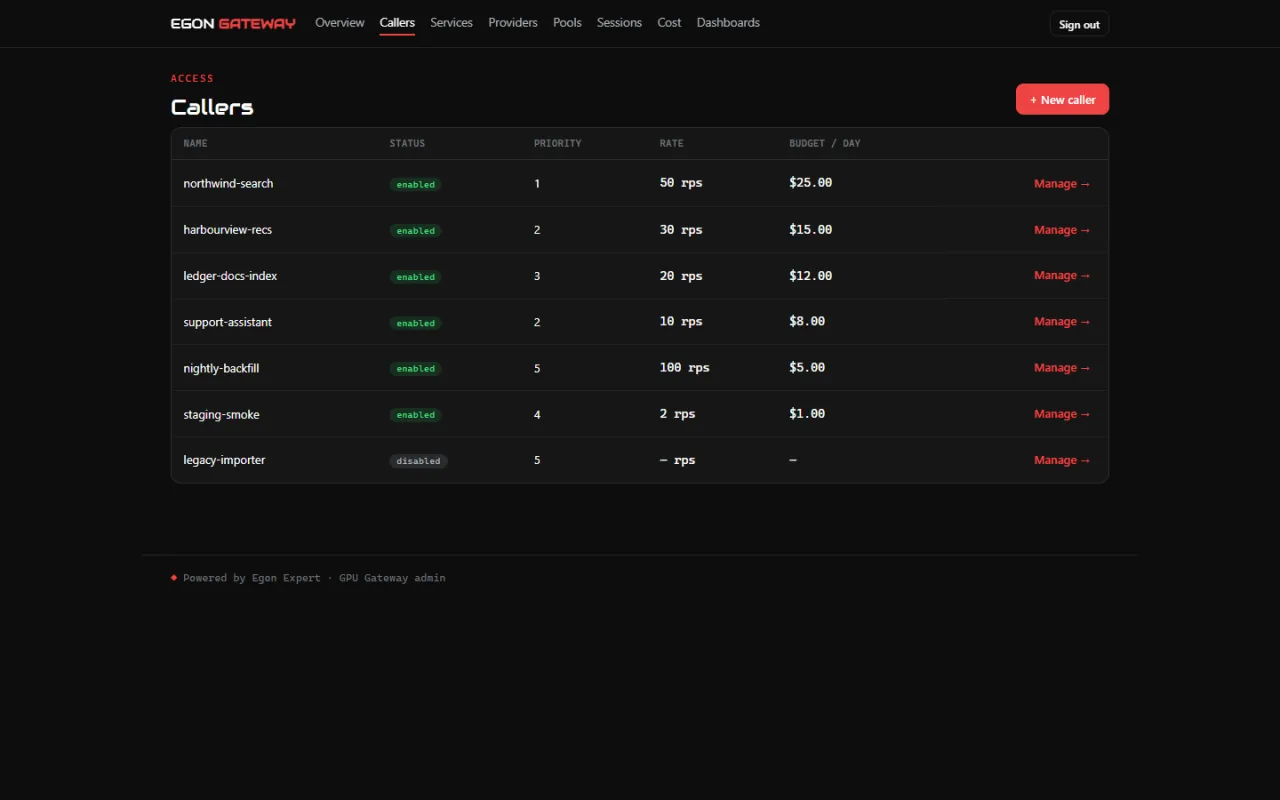
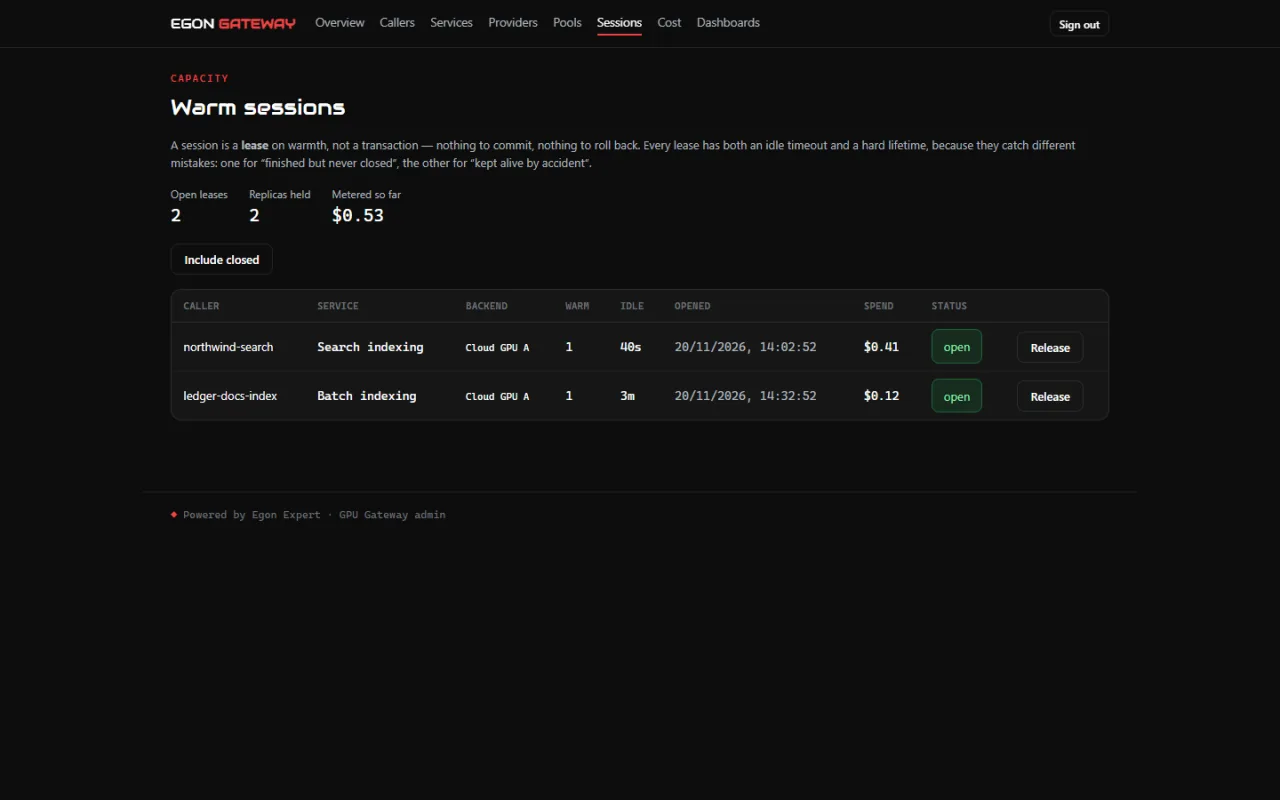
Every screenshot shows demo data: the organisations, people and figures are made up.
Why It Exists
Several of our products need GPU work: search indexing, speech-to-text, vision. Letting each one hold its own GPU account means paying several times for idle capacity, with no shared view of what is spent. The research behind it settled on buying managed APIs where they are cheap enough and using serverless GPUs, behind one gateway, for the rest. The same question comes up in our AI cost advice to clients: rent, buy or call an API.
What It Is Worth
No silent GPU bills
Warm capacity on metered backends is flagged as billed, idle leases are visible and releasable, and every caller has a daily budget.
Provider choice in configuration
Moving a workload between providers, or onto our own hardware, is a configuration change, with fallbacks in a set order.
Hardware we own earns its keep
Spare capacity on machines we own can take work through the same gateway, and steps back automatically when the machine is needed locally.
Who It Helps
Product teams
Call one API for GPU work, with caching and queuing included, instead of integrating and paying for a GPU provider in each product.
Whoever pays the bill
See volume, spend and failures per caller and per provider in one console, with budgets enforced before the work runs.
At a Glance
| Status | Internal: runs inside Egon Expert Ltd and is not sold on its own; Late prototype |
|---|---|
| First workload | Indexing text for AI search |
| Capacity | Rented serverless GPUs and machines we own |
| Built by | Egon Expert Ltd |
Related Products
Need Something Like This?
We build platforms like GPU Gateway for clients, and help in-house teams build their own. Start with a free 30-minute conversation about what you need.
Book a Free Consultation